
Original English rap · Fictional adults
AI friendly roast rap video: a two-person English example
This friendly roast uses two fictional adult reference images and a topic about being late, bringing snacks and drinking coffee. The actual 15-second vertical output contains model-generated English vocals and music, with two performers in a street setting. The brief asks for affectionate teasing between friends.
Published October 26, 2026 · 15 seconds · 720 × 1280 · 9:16 · English audio
The reference images and topic
These two AI-generated images supplied the fictional adults for this test, in input order. They are demonstration materials, not customer photos.
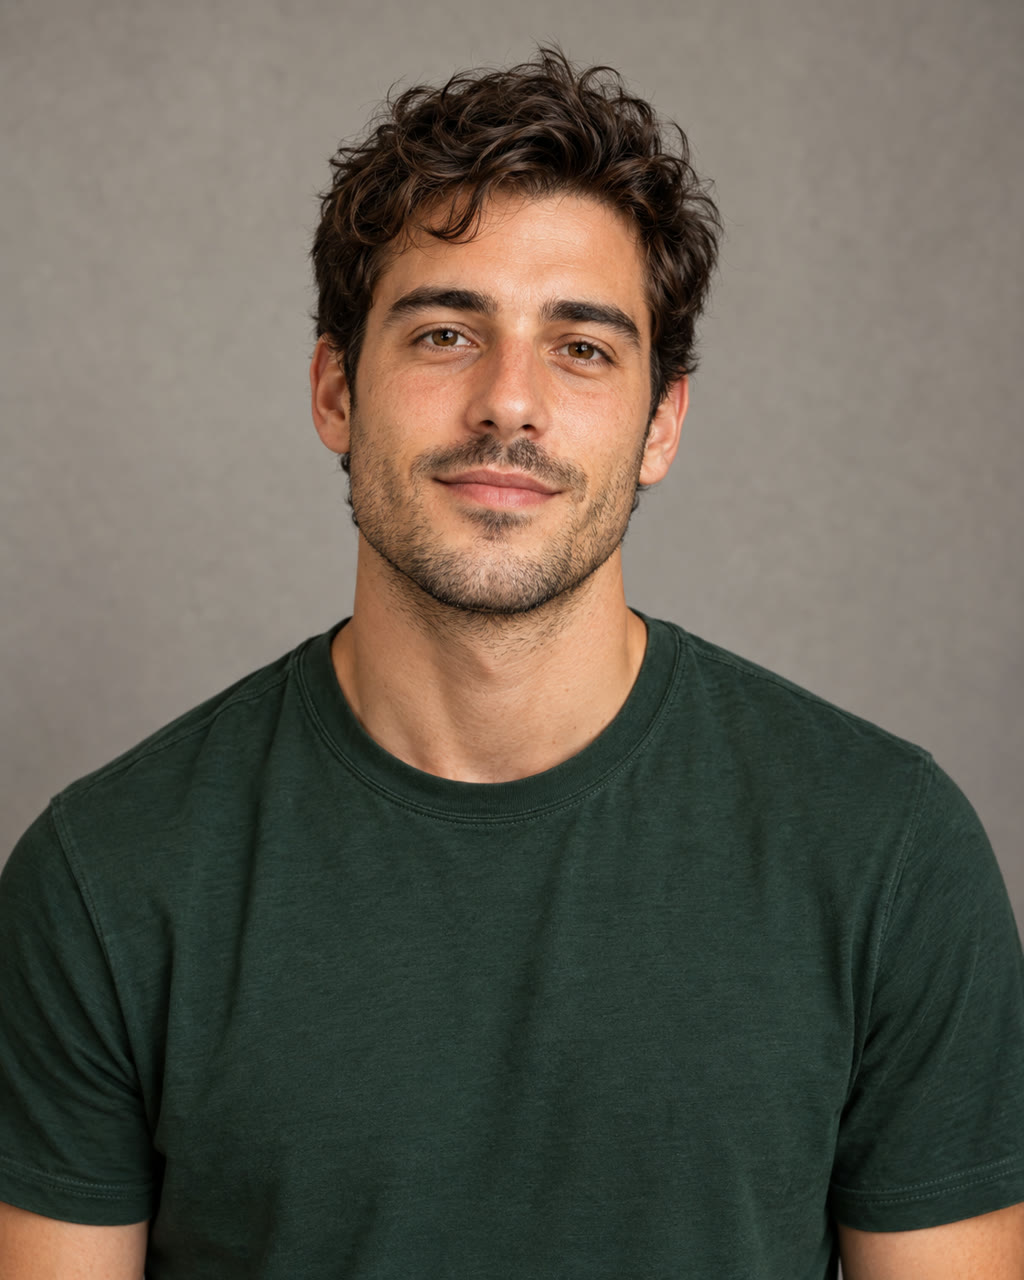
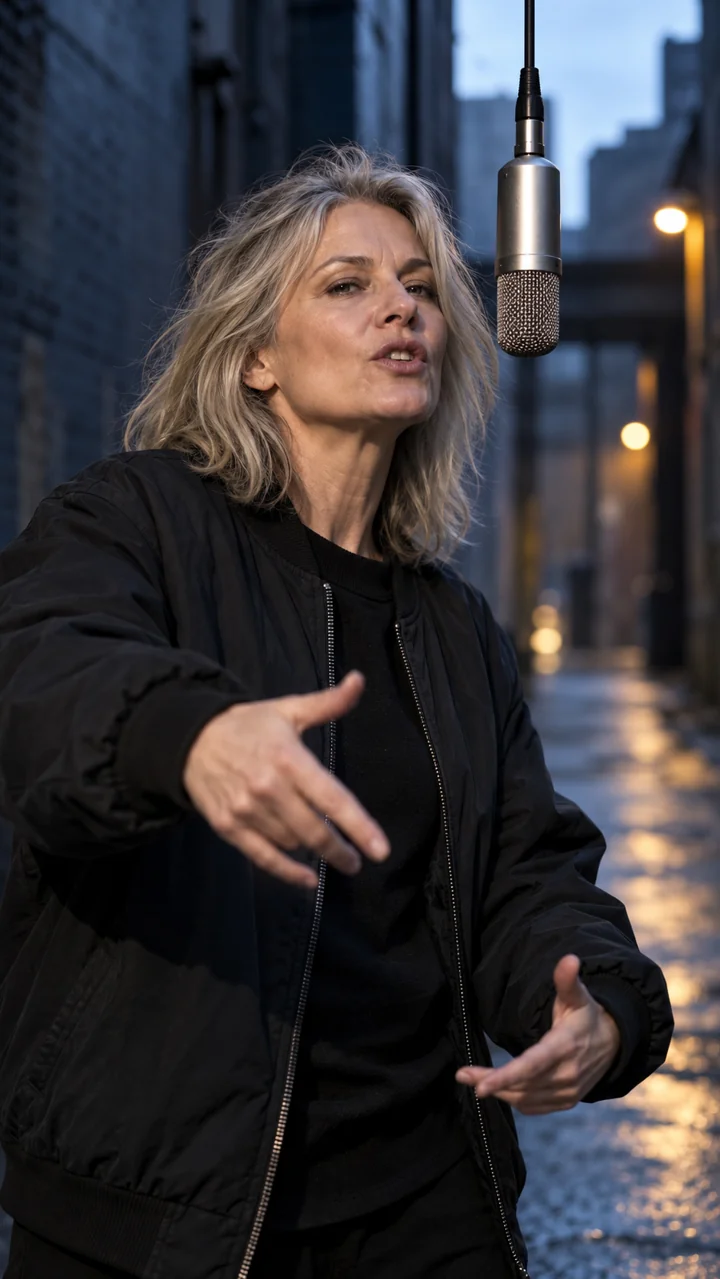
Topic supplied: Alex jokes Riley is always late but brings great snacks. Riley replies Alex lives on coffee. Celebrate their friendship.
Pick a harmless shared habit and end on friendship. Ask both adults for permission to use their images and agree on the joke before sharing. Leave private information, appearance-based insults and sensitive experiences out of the topic.
What this output shows
The sampled frames show two distinct performers, a shared microphone in the central gap and unobstructed faces. Early and later mouth activity corresponds to different performers. Automatic transcription found lateness, snack and coffee references, with recognition errors; it does not prove exact turn timing or word-perfect lyrics.
The requested music direction was Light drill. That label describes the creative brief, not an independently verified music classification. The video was generated with SeeAPI Seedance 2.0 Fast from image references, without an uploaded song, audio reference or cloned voice. The public MP4 is a compressed copy of the output with its generated audio retained.
What the review established
Review covered full video decoding, media structure, one sampled frame per second and automatic English speech recognition for topic relevance. It did not include a human listening review. There is no verified lyric transcript, so this player does not reuse captions from a different sample. Listen to the full clip to assess the sound yourself.
Names, faces, hands, camera framing and lip timing can vary. This single example does not establish a success rate or guarantee a matching result for another photo. Original rap makes new audio from a topic; the olderOrange Studio template test retains its reference soundtrack.
Can I make my own?
The creation console is in preview. You can explore its photo, topic, solo/duo, vocal-language and 9:16/16:9 controls, but customer generation and checkout remain closed during validation. This portrait example does not establish native landscape quality. Only use photos of adults who have given permission.